KitOps - 7 min read
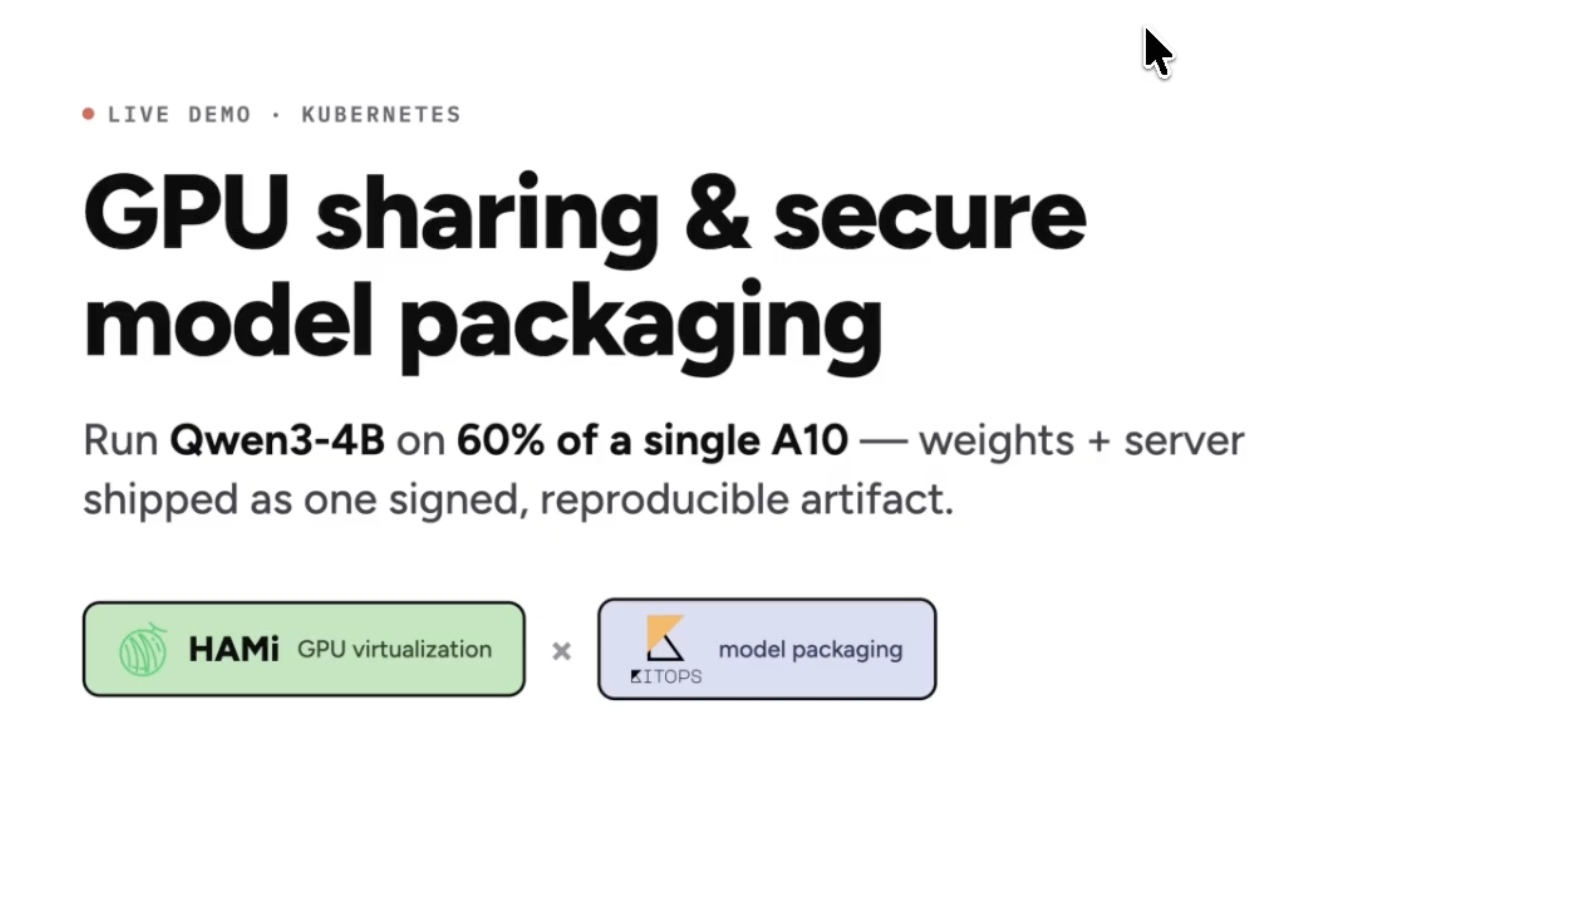
Run Qwen3 4B on 60% of a GPU with HAMi and KitOps
Run a Qwen3 4B model on a fractional GPU slice on Kubernetes, with the vLLM server and weights shipped as one signed, reproducible OCI artifact. A walkthrough using Project HAMi for GPU virtualization and KitOps for model packaging.