
ai - 9 min read
95 posts by Jesse Williams
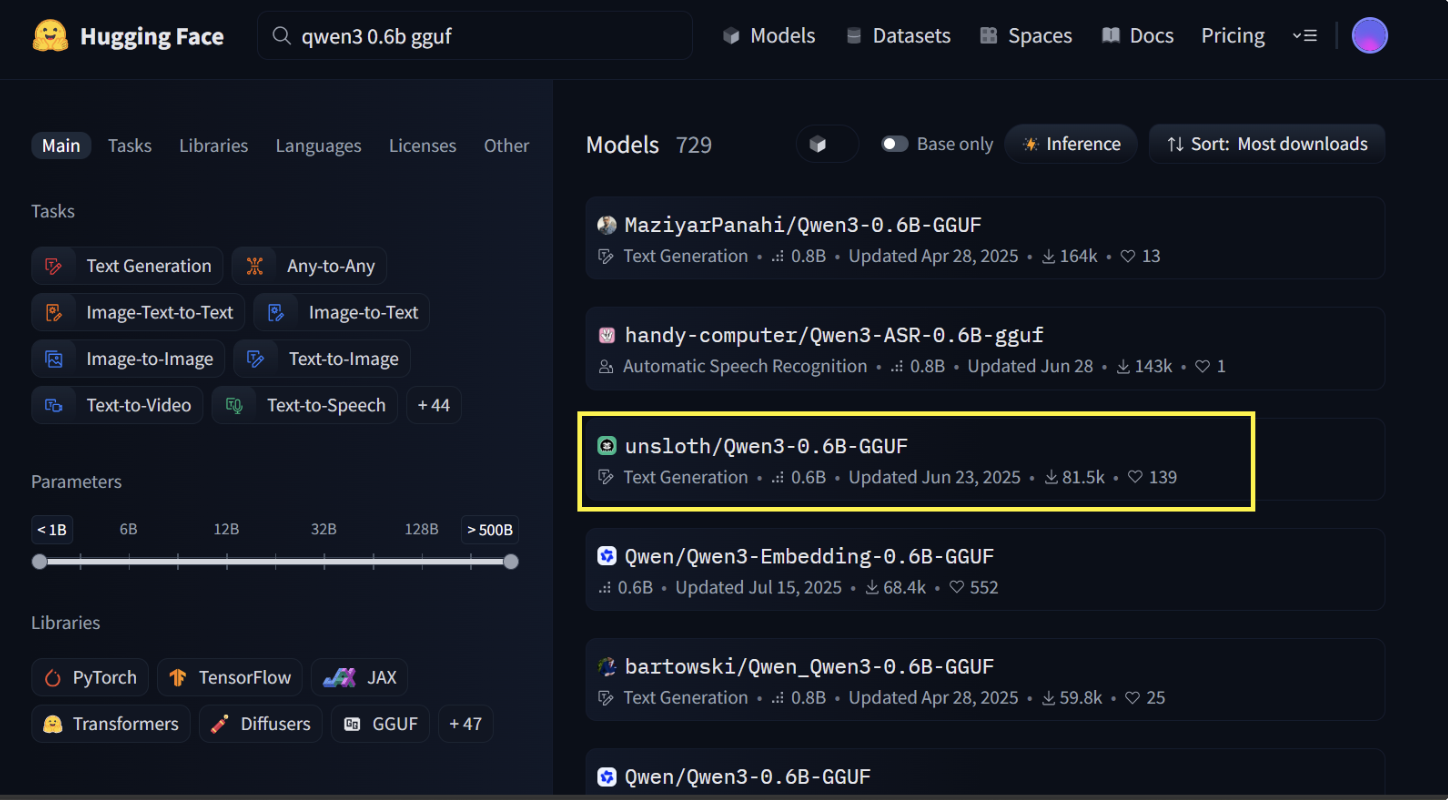
Learn how speculative decoding pairs a small draft model with a large target model to speed up local LLM inference, and how to run it with Jozu Rapid Inference Containers.
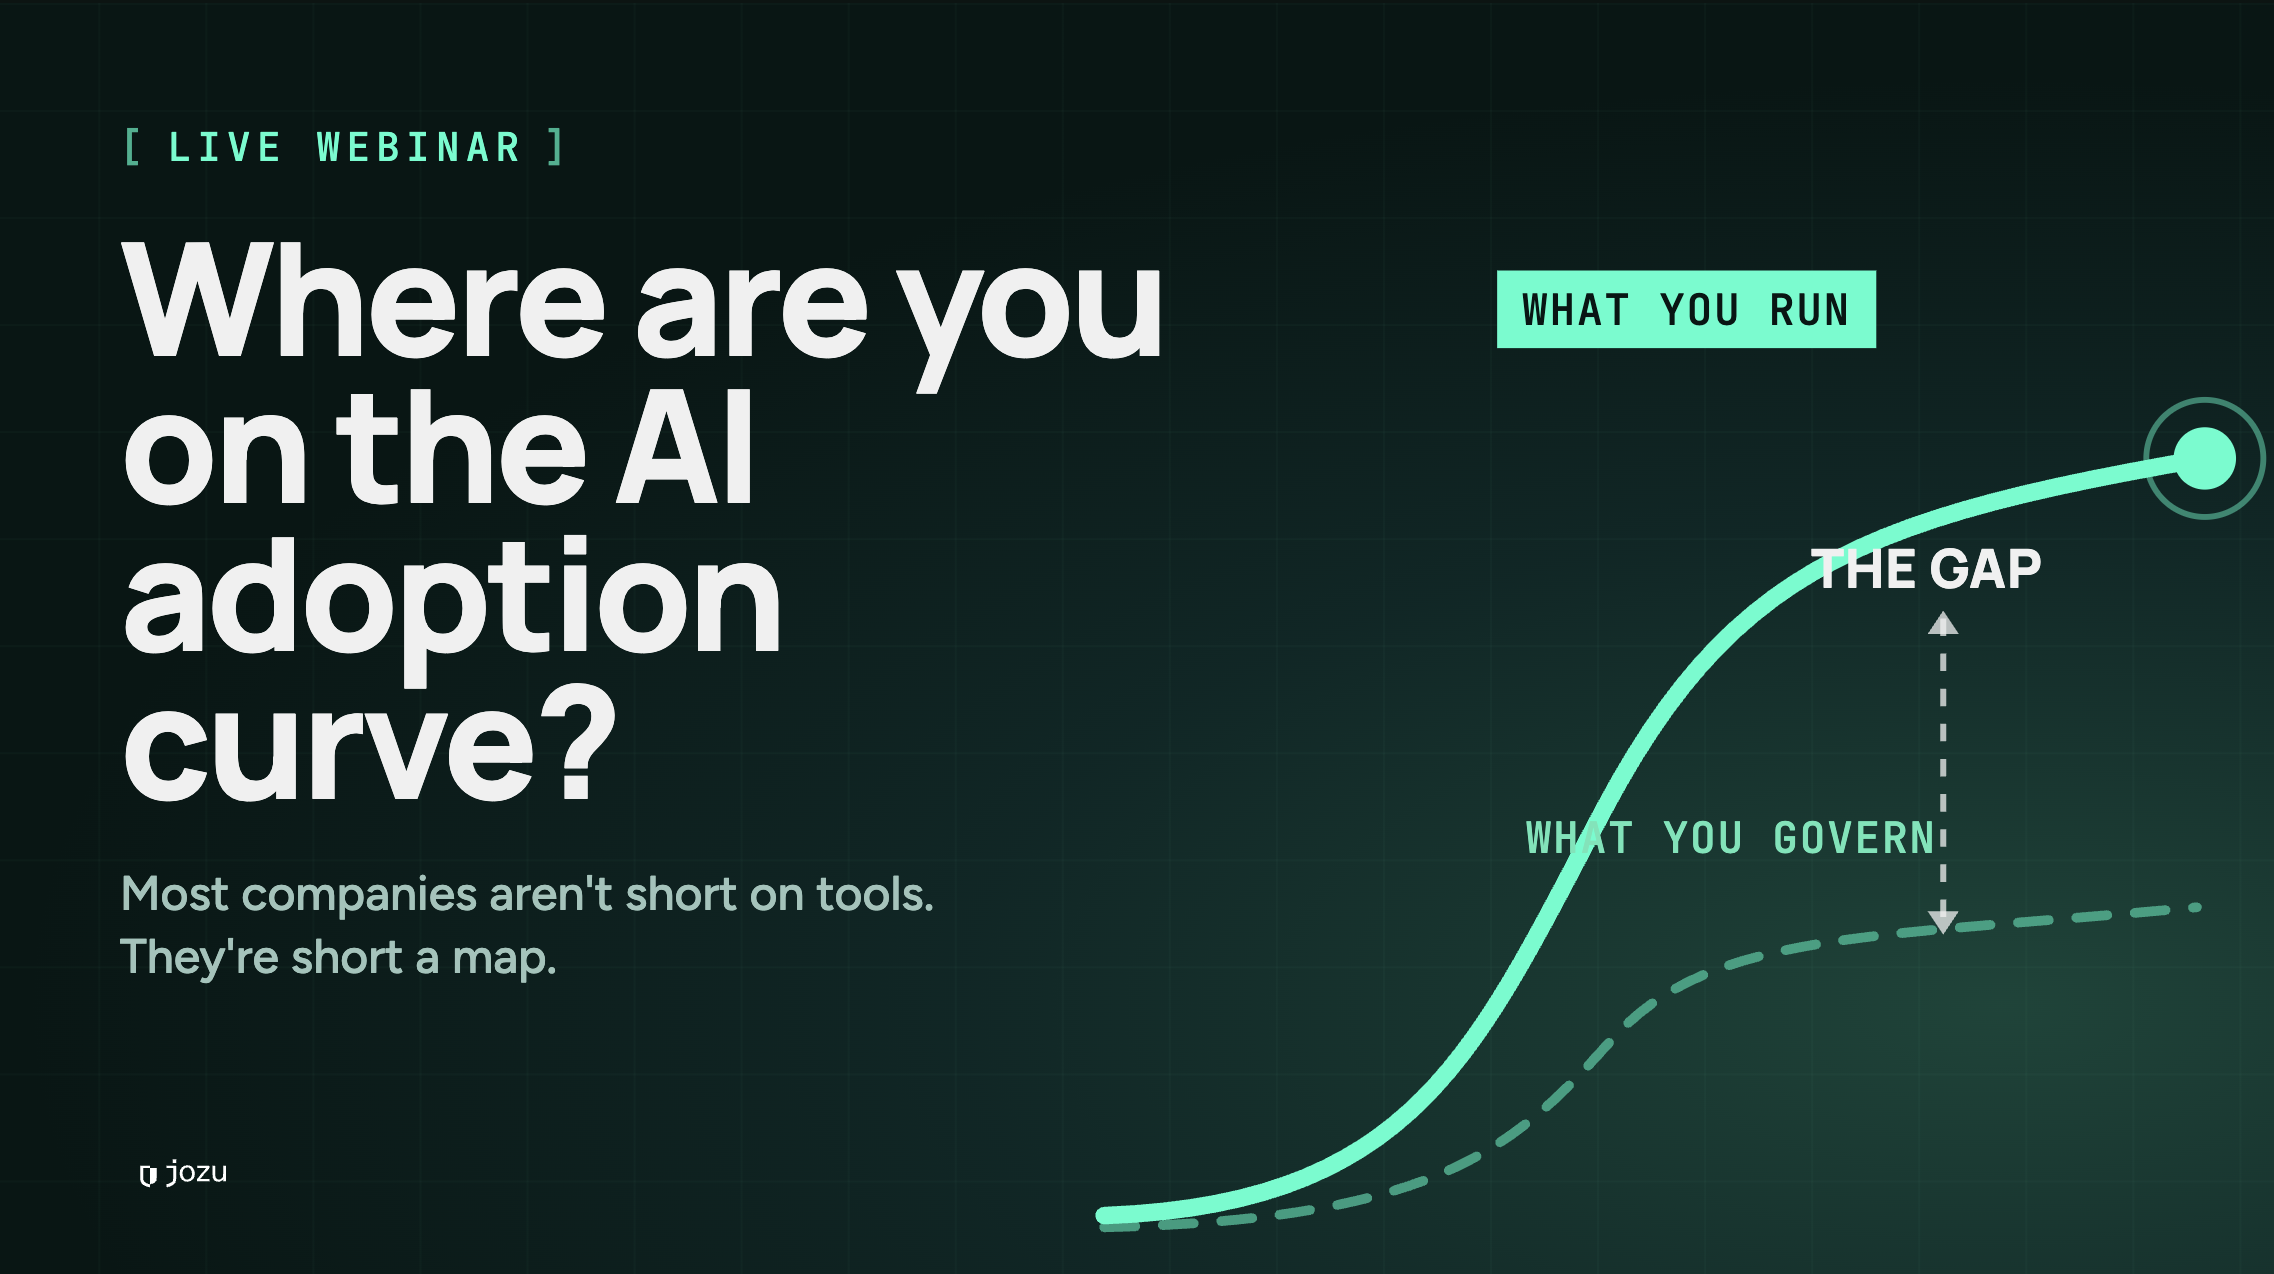
Recap of our webinar with Jozu CEO Brad Micklea: the five levels of AI adoption, the two gaps that get organizations hurt (the AI supply chain and the runtime), real-world attacks, and four actions to take this quarter.
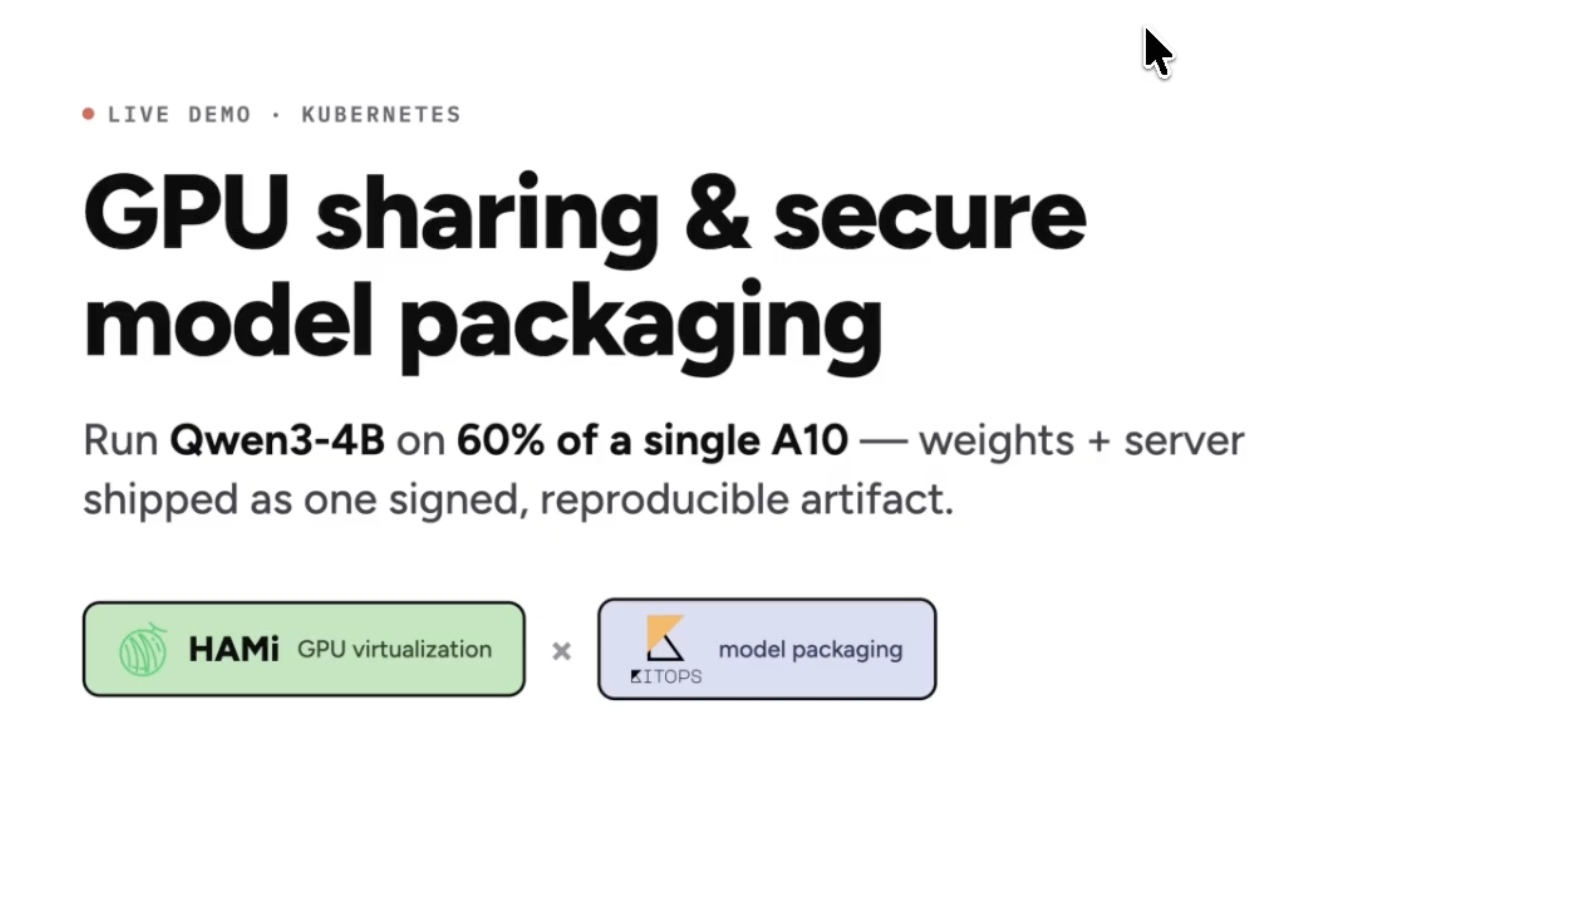
Run a Qwen3 4B model on a fractional GPU slice on Kubernetes, with the vLLM server and weights shipped as one signed, reproducible OCI artifact. A walkthrough using Project HAMi for GPU virtualization and KitOps for model packaging.