Accelerate Local AI Inference with Speculative Decoding on Jozu RIC
Learn how speculative decoding pairs a small draft model with a large target model to speed up local LLM inference, and how to run it with Jozu Rapid Inference Containers.
32 posts in machinelearning
Learn how speculative decoding pairs a small draft model with a large target model to speed up local LLM inference, and how to run it with Jozu Rapid Inference Containers.
Run a Qwen3 4B model on a fractional GPU slice on Kubernetes, with the vLLM server and weights shipped as one signed, reproducible OCI artifact. A walkthrough using Project HAMi for GPU virtualization and KitOps for model packaging.
A self-hosted MCP registry gives enterprises a single, signed source for approved MCP servers. Learn what it covers and why GitHub repos are not enough.
A practical agentic AI governance framework covering policies, tool access, runtime enforcement, and audit trails for security and platform teams.
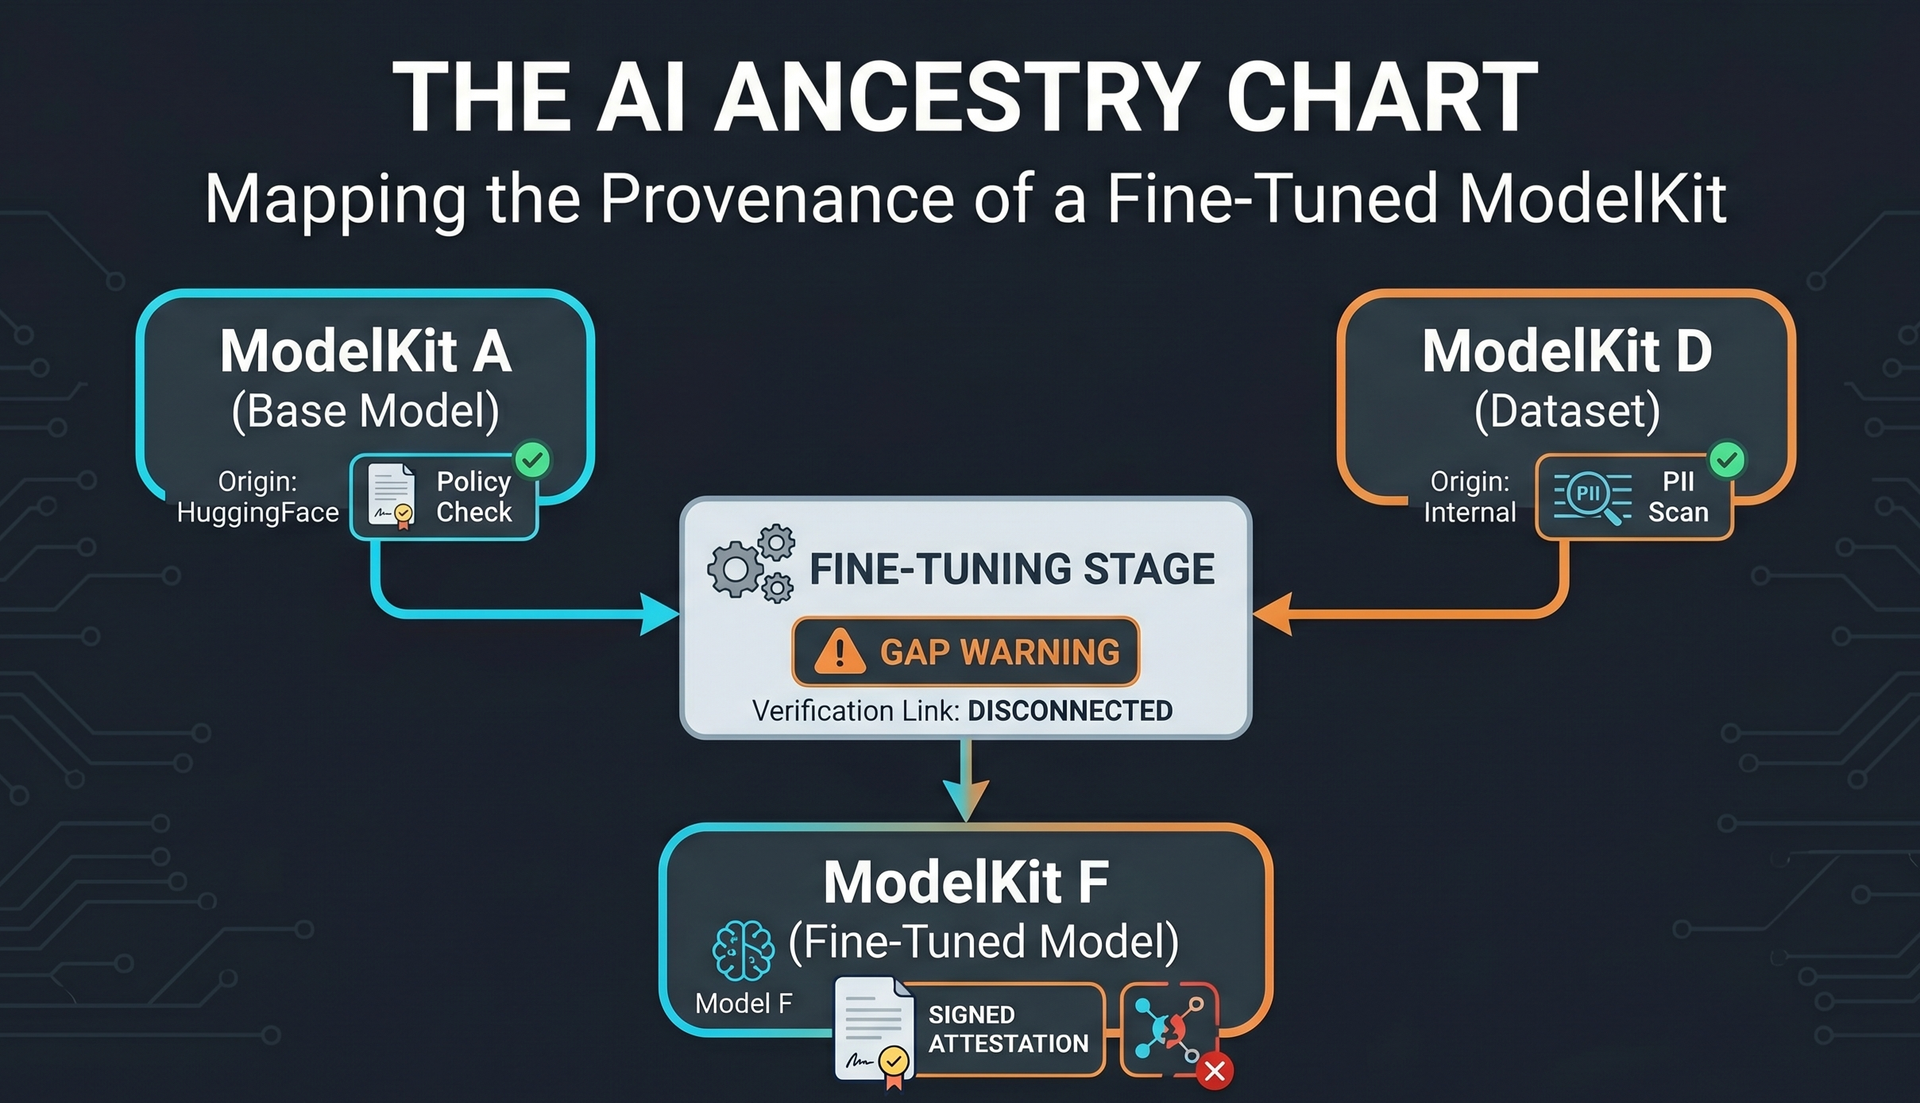
Signing your AI models isn’t enough. Learn why fine-tuned model provenance requires graph traversal, not just attestations, to close the supply chain gap.
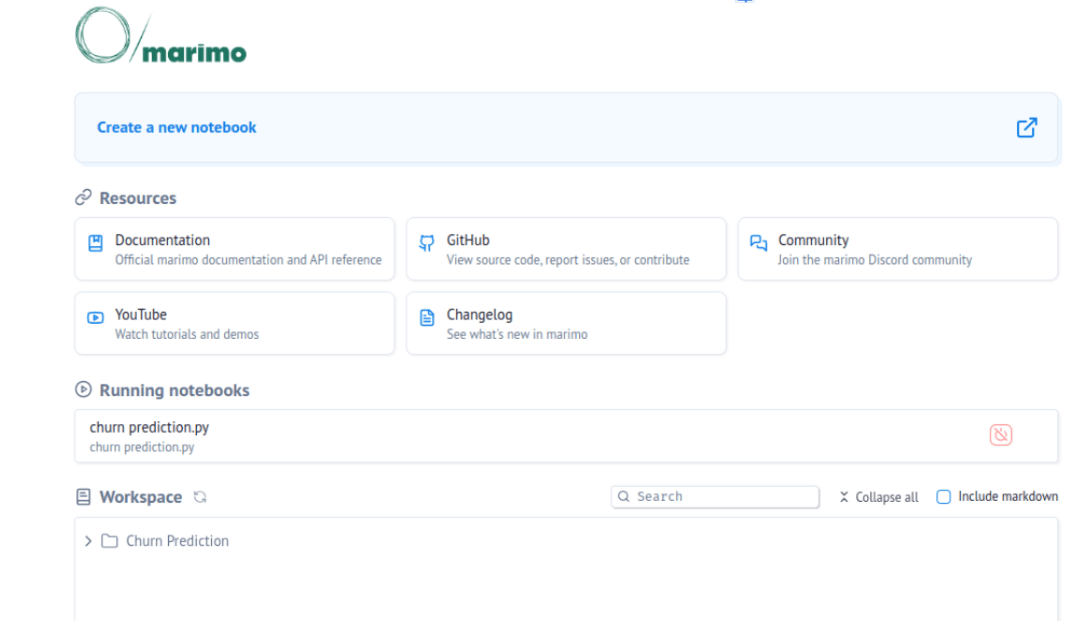
Learn how to transform your ML training notebooks into deployable ModelKits using KitOps and Marimo. This comprehensive tutorial covers packaging your machine learning models with all dependencies, datasets, and code into a single, shareable artifact for seamless deployment.